Tools / Pinecone
About Pinecone
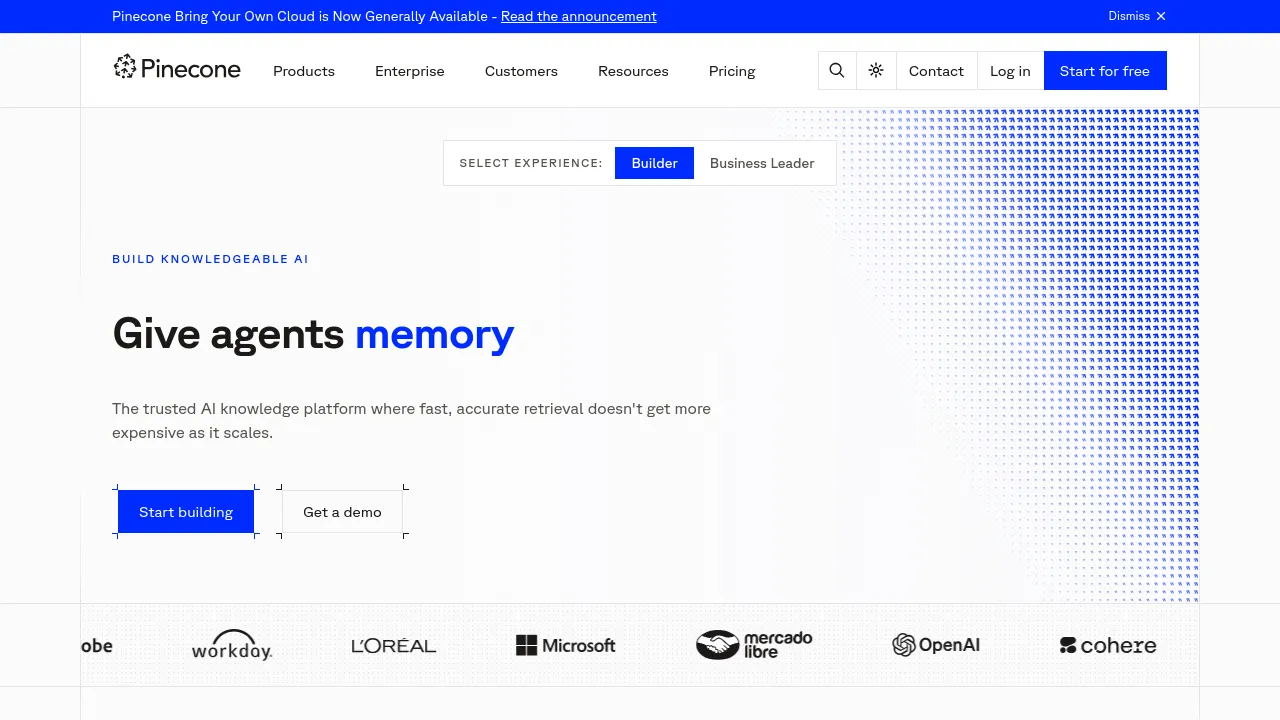
Pinecone is a fully managed vector database built for AI applications like RAG and semantic search. You write vectors through an API, and Pinecone handles indexing automatically — writes are acknowledged in under 100ms and become searchable within seconds, with no index tuning required. Queries run in parallel across all data, and the site claims latency holds steady as scale grows. Indexes support dense vectors, namespaces, filtering, and reranking, all managed from a web console (app.pinecone.io) or the API. The console shows record counts, read/write units, request latency percentiles, and storage size per index. Pinecone also offers a product called Nexus, a "knowledge engine" that compiles enterprise data into a governed knowledge base served through a single query — the company's benchmarks claim 85–97% fewer tokens per query and up to 30x faster completion versus agentic RAG in three tested domains. On the enterprise side, Pinecone supports encryption at rest and in transit, SSO, RBAC, CMEK, private networking, and a Bring Your Own Cloud deployment option (recently announced as generally available). It is certified for SOC 2 Type II, HIPAA, GDPR, and ISO 27001, with uptime and support SLAs. Integrations include plugins for Claude Code, Cursor, GitHub Copilot, Codex, and Gemini CLI, plus an MCP server and a direct REST API. Customers named on the site include Adobe, Workday, Microsoft, OpenAI, Cohere, Zapier, and The Washington Post. Pricing starts free, then pay-as-you-go; the site includes a workload cost estimator.
What it does
Pinecone stores and searches vector embeddings. The core workflow: create an index, upsert records through the API or an integration plugin, then search, filter, and rerank from the same index. Indexing is automatic — the service picks algorithms based on data size and rebalances in the background, so there's no infrastructure to tune.
Products
- Vector Database — the core managed index service, with dense vector support, namespaces, backups, and imports.
- Nexus — a knowledge engine that compiles enterprise data into governed knowledge served through a single query, positioned as an alternative to multi-step agentic RAG.
- Assistant and Dedicated Read Nodes — listed as separate products on the site.
Integrations
Pinecone ships plugins for Claude Code, Cursor, GitHub Copilot, Codex, and Gemini CLI, plus an MCP server and a direct API. One API key covers search, upsert, and rerank.
Console and observability
The web console at app.pinecone.io lets you create and manage indexes, browse records, run test queries, and view metrics: read/write units, requests per second, query/upsert/update/delete/fetch latency (p50/p95/p99), storage size, and record count.
Enterprise and compliance
Encryption at rest and in transit, SSO, RBAC, CMEK, and private networking. Certifications listed: SOC 2 Type II, HIPAA, GDPR, ISO 27001. Uptime SLAs and support SLAs are mentioned. Bring Your Own Cloud is generally available.
Pricing
Free tier to start, then pay as you go. The homepage includes a cost estimator where you describe your workload (e.g., a RAG pipeline for a production app) and get an estimate. Full pricing is at pinecone.io/pricing.
FAQ
Is there a free tier? Yes — the site says you can create your first index for free and pay as you go when scaling.
Which cloud does it run on? The console screenshots show indexes on AWS regions (us-east-1, us-west-2, eu-west-1). A Bring Your Own Cloud option is also generally available.
Does it support sparse vectors? The site's examples show dense indexes; the docs would be the place to confirm sparse support.
How fast are writes searchable? Writes are acknowledged in under 100ms and searchable within seconds, per the site's architecture description.
Who uses it? Customers named on the homepage include Adobe, Workday, L'Oréal, Microsoft, Mercado Libre, OpenAI, Cohere, Fox, The Washington Post, Asana, Gong, Expensify, Cisco, Zapier, Sanofi, and Vanguard.
Similar tools? The alternatives listed for this category are AI coding tools (Cursor, Claude Code, GitHub Copilot, etc.), which serve a different purpose than a vector database — none are a direct match.
Similar to Pinecone
New tools, once a week.
One weekly email with curated tools and founder insights. Unsubscribe anytime. Check our privacy policy.